PlugRL
PlugRL trains a policy against environments that run somewhere else: in another process, on another machine, on a machine with no GPU, or in a program that is not Python. A training server holds the policy and the algorithm; env clients step the environments and ask it for actions. Between them is a written protocol that carries the rewards and episode ends back as well as the actions out, so the policy is trained, not only served.
What runs on it
Every combination of the two MLP policies and the two algorithms on four tasks, and the baseline they are measured against, a Gaussian MLP with PPO. All sixteen learn. The border and its label say what the experiments found. The line under each clip is the training curve of all three seeds (the return; on square, the success rate, since those runs do not share a reward), drawn on one scale per column, so a flat line really is flat. Hover over a cell to play it; click or tap it to play it and see the two commands that trained it. From one cell to the next, only the words that name the policy, the algorithm and the task change.
On square every row fine-tunes a pretrained policy: dppo-policy and the
Gaussian MLP start from DPPO's released checkpoints, fpo-policy from a
behaviour-cloned start of our own
(E35).
The Gaussian MLP row is CleanRL's policy and PPO on the three MuJoCo tasks,
where it ends about where CleanRL's own runs do
(E38),
and DPPO's Gaussian MLP with DPPO's own PPO settings on square
(E40).
dppo-policy · FPO is missing because it cannot exist: FPO trains flow
policies only. Each clip comes from the final checkpoint of the seed whose
last ten iterations were the median of three. That checkpoint was evaluated
for five episodes, and the clip is the episode with the median return, not
the best one. The scripts that made all of this are in
figures/coverage.
The two sides do not even share a Python environment. None of the servers that trained these cells has MuJoCo, robosuite or gymnasium installed. The env clients ran in two separate environments: gymnasium with MuJoCo 3 for the MuJoCo tasks, and robosuite 1.4.1 with MuJoCo 2.3.7 for robomimic, because robosuite 1.4.1 does not run on MuJoCo 3. One server codebase trained all sixteen.
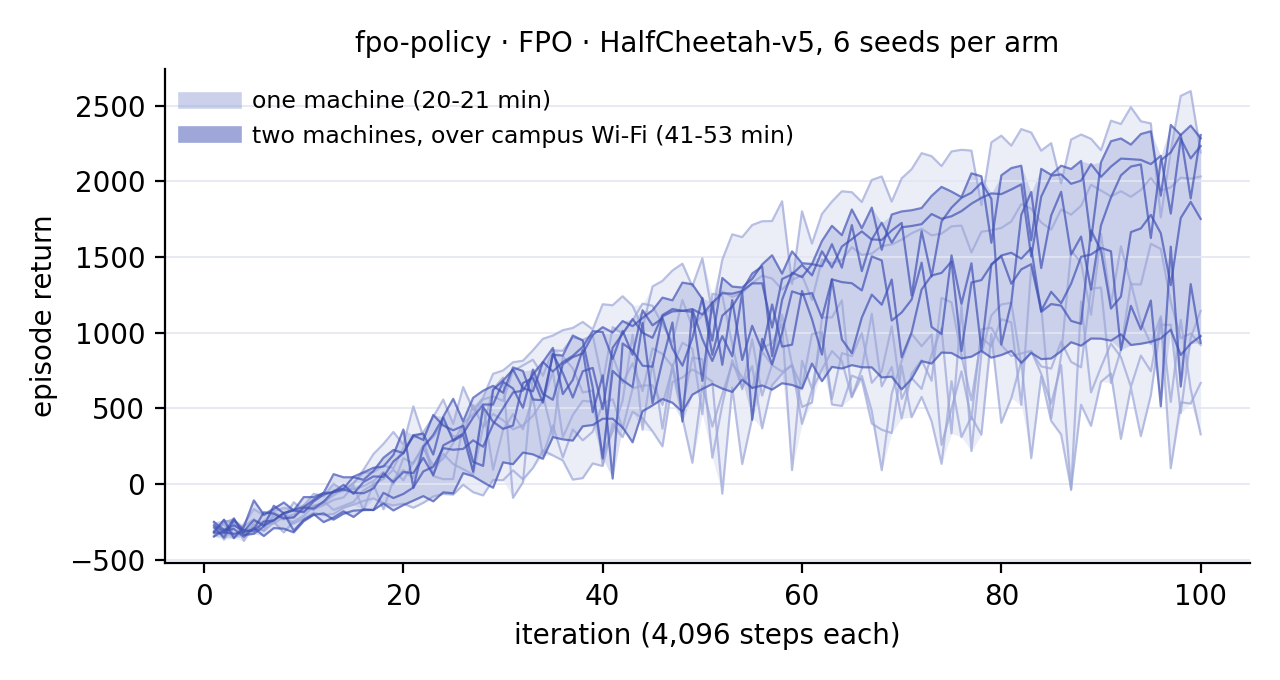
The same pair also learns with its env clients on another machine: a Windows laptop on campus Wi-Fi steps HalfCheetah for a server on a Linux workstation. Six seeds on each side fall within one band. Across the two machines, a run took 41-53 minutes instead of 20 (E43).
The environment side is light
The training server is 6.5G and wants a GPU. The machine running environments needs neither. A LIBERO env client installs at 3.4G with no nvidia wheels instead of 7.8G with sixteen, sends byte-identical observations, and renders on the CPU: ten clients at once, 30 of 30 episodes successful, at 1.91x the wall clock of the same run on a GPU (E12, E13). Stepping is 10x slower in software, and most of that hides behind the queue of clients waiting on one policy.
It is lighter than the other systems that train through their channel, too.
plugrl-env-client installs 31 packages, 222 MB, with no torch, and the C++
client below is an 86 KB binary. RLlib's external-env client and LeRobot's
HIL-SERL actor each install about 6.1 GB, torch and 15 CUDA packages among
it, because both run the policy on the environment side. A thin environment
side alone is not new: dm_env_rpc's and openpi's clients are smaller still,
but neither trains through its channel
(E45).
It does not have to be Python either. The protocol is written down, with a conformance checker. A C++ program with nothing beyond the standard library - no msgpack or WebSocket library - steps its own copy of Pendulum and trains a policy through it, as well as the Python env client does (E44).
Other trainers train through it
The protocol is not tied to PlugRL's own server. Small adapters present it as
the environment interface a trainer already has
(plugrl-bridges). Through them, three trainers that were not written for PlugRL train
PlugRL env clients, and every seed of every pairing learns:
- RLinf's PPO, on the C++ Pendulum client;
- Stable-Baselines3's PPO, on the C++ Pendulum client and on HalfCheetah;
- CleanRL's PPO, on HalfCheetah
(E49).
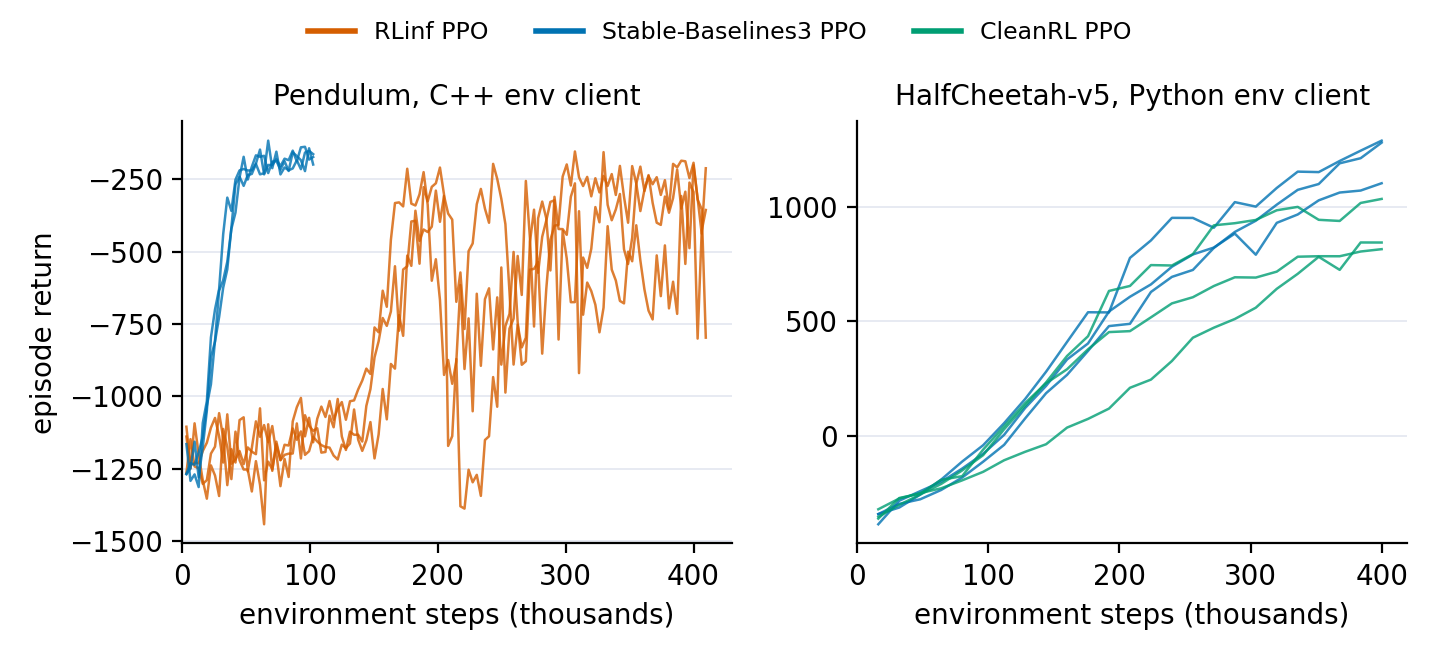
Each line is one seed's mean return over its 16 env clients, from the bridge's own episode log. RLinf learns Pendulum later than Stable-Baselines3 at the same settings; E49 records that and does not explain it.
RLinf also trained 16 HalfCheetah env clients that ran on a laptop with no torch, Ray or RLinf, in a 276 MB environment (E48).
Behind the protocol, training sees nothing different. Stable-Baselines3 with its 16 environments in another process ends on the same weights, byte for byte, as with them in its own process: on Pendulum and HalfCheetah (E50), on Atari frames with a CNN (E53), and with every byte between the two sides held up to 25 ms each way (E52). Only the time changes: 0.4-0.6 ms per step of 16 environments on one machine, 2.6-3.0 ms when each step carries 16 frames, and about two one-way delays per step behind a slow link.
When the boundary is wrong, nothing says so
67 seconds, no sound: one value changed on its way to the trainer, a learning curve that rises anyway, and the step ledger that finds the change.
The same bridge let us ask how a broken boundary shows itself. While SB3's PPO trained Pendulum, HalfCheetah, Hopper and Pusher, a 7-joint arm, the env client changed one field of what crossed, in one way: an observation, action, reward or final observation zeroed, stale, swapped with the next environment's or rounded to float16, an episode end invented or sent as the wrong kind, a step skipped. Nothing raised an error. Unless every value was wrong, the learning-curve threshold we had relied on caught at most one run in ten, and a comparison with ten fault-free seeds at most 21% (E54, E56, E58). A clean evaluation of every final policy agreed with the curves: of the 728 boundary-fault runs that passed both curve checks, 723 scored like fault-free seeds (E57). The runs were not the same runs, though. Nearly all ended on other weights, and reward faults changed the returns the trainer logged.
What saw every fault was a check of the run itself. A step ledger keeps a
record on each side of the boundary, what each environment took and gave and
what the trainer sent and received, and compares the two step by step. On
one machine it caught and located all 585 boundary-fault runs on Pendulum,
Hopper and Pusher, and across two machines all 21 on Pendulum, with no
fault-free run to compare against, for a median 3% of training time on
Pendulum (E55;
Hopper and Pusher in E56 and E58).
An episode record kept at the environment caught the faults planted in the
trainer's own log. Such faults happen outside experiments too: under
SAME_STEP autoreset, Gymnasium 1.3's vector episode statistics dropped the
first reward of every episode after an environment's first, until 1.4
(E51).
The step ledger is now a package of its own,
step-ledger, for Gymnasium and
Stable-Baselines3 with or without PlugRL. Wrap each environment in
LedgerEnv and the vector env the trainer sees in LedgerVectorEnv (or
LedgerVecEnv for Stable-Baselines3); after the run, stepledger compare
names the environment, episode, step and field of the first difference. Each
side adds a few microseconds per environment step.
This is the paper Detecting Silent Faults at the Environment-Trainer Boundary in Reinforcement Learning, accepted to the CoRL 2026 Workshop on Everything Beneath the Policy (PDF; citing it).
What the split costs
On one machine, almost nothing: an exchange takes 0.1 ms with states only and
under 1 ms with a 588 KiB observation. Between two machines it becomes two
terms:
- A fixed latency. About 3 ms between a laptop on Wi-Fi and a
workstation, over Tailscale.
- The observation's bytes over the link's bandwidth, once. The feedback
that ends a chunk carries the observation, and with reuse-feedback-obs, a
feature the server offers and the env client uses by default, the next
request for actions leaves it out.
On a 23.7 MB/s link, a state-only task pays about 3 ms per step, and a 184 KiB camera observation 11.6 ms, against 18.5 ms when each observation crossed twice. Training ends on the same weights, byte for byte, either way (E46; E43 measured the first version). A faster link shrinks the second term in proportion.
A real VLA, end to end
The unmodified pi0.5, driven through the boundary on libero_spatial
task 0 - three episodes, all three successful. This is the observation stream
the policy itself sees, at its native 224x224, not an outside camera.
The same two processes carry a full-size pi0.5. The env client steps LIBERO
and the server answers with actions; nothing about the boundary changes, only
the policy does. The unmodified checkpoint scored 99 of 100 on
libero_spatial and 185 of 200 on libero_10, against openpi's published
98.8 and 92.4, and the server's episode and step counts matched the clients'
exactly, which is what says the transport dropped nothing
(E11).
Fine-tuning pi0.5 with reinforcement learning through PlugRL has not made it better yet. That record, with clips, is on its own page.
Quickstart
A pair that learns without a GPU: FPO on HalfCheetah-v5, CPU only, with no assets to download. Neither package is on PyPI, so install both from source:
git clone https://github.com/PlugRL/plugrl-server.git
git clone https://github.com/PlugRL/plugrl-env-client.git

cd plugrl-server     && uv sync && cd ..
cd plugrl-env-client && uv sync --extra mujoco && cd ..
Then, in two terminals, each inside its own repository (uv run uses that
repository's .venv):
# Terminal 1, in plugrl-server - the training server
uv run plugrl-run-server fpo-policy default fpo default \
    --port 8000 --policy.device cpu \
    --algo.global-steps 500000 --algo.buffer-size 4096

# Terminal 2, in plugrl-env-client - the environment
uv run plugrl-run-env-client mujoco-v1 \
    --server-host 127.0.0.1 --server-port 8000 \
    --num-envs 1 --num-episodes 600 --runner.replan-steps 1 --runner.seed 0
Episode return starts near -300 and reaches 1928 ± 224 by 500k steps
across three seeds, roughly a hundred minutes on the CPU-only machine that
measured it
(E6).
Get Started has the rest: why
--algo.buffer-size matters, a connectivity check, and troubleshooting.
Components
plugrl-server: training server, runs algorithm, policy, checkpoints, trackingplugrl-env-client: environment runner, collects rolloutsplugrl-protocol: transport, message types, and serialization (WebSocket + msgpack)
Envs, policies and algorithms can live in your own packages, registered on the side that uses them.
Next steps
Citing
If the boundary checks are useful to you, cite the paper: